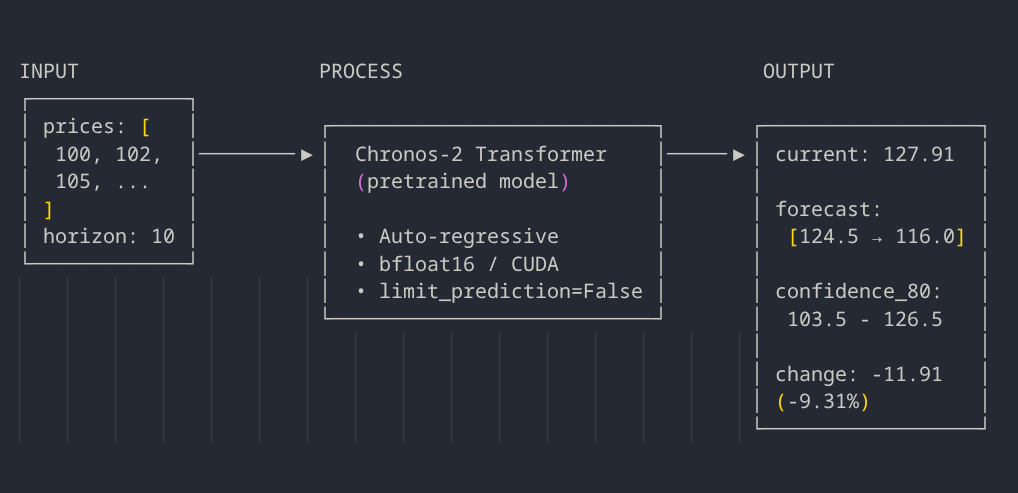
INPUT                    PROCESS                              OUTPUT
┌─────────────┐
│ prices: [   │          ┌───────────────────────────┐       ┌──────────────────┐
│  100, 102,  │────────▶│  Chronos-2 Transformer    │─────▶│ current: 127.91  │
│  105, ...   │          │  (pretrained model)       │       │                  │
│ ]           │          │                           │       │ forecast:        │
│ horizon: 10 │          │  • Auto-regressive        │       │  [124.5 → 116.0] │
└─────────────┘          │  • bfloat16 / CUDA        │       │                  │
                         │  • limit_prediction=False │       │ confidence_80:   │
                         └───────────────────────────┘       │  103.5 - 126.5   │
                                                             │                  │
                                                             │ change: -11.91   │
                                                             │ (-9.31%)         │
                                                             └──────────────────┘
from bottle import post, get, run, request, HTTPError
import torch
from chronos import Chronos2Pipeline
import os

CACHE_DIR = os.path.join(os.path.dirname(__file__), "models")
os.makedirs(CACHE_DIR, exist_ok=True)

device = "cuda" if torch.cuda.is_available() else "cpu"
pipeline = Chronos2Pipeline.from_pretrained(
    "amazon/chronos-2",
    device_map=device,
    dtype=torch.bfloat16,
    cache_dir=CACHE_DIR,
)

@post('/api/stock-forecast')
def stock_forecast():
    data = request.json or {}
    prices = data.get('prices', [])
    horizon = data.get('horizon', 5)

    if not prices or len(prices) < 5:
        raise HTTPError(400, 'At least 5 historical prices required')

    current_price = prices[-1]

    try:
        context = torch.tensor([prices], dtype=torch.float32).unsqueeze(1)
        with torch.no_grad():
            predictions = pipeline.predict(
                inputs=context,
                prediction_length=horizon,
                limit_prediction_length=False,
                batch_size=256
            )

        q = predictions[0].squeeze(0).cpu().numpy()
        median_idx = 4
        lower_idx = 1
        upper_idx = 7

        return {
            'current_price': round(current_price, 2),
            'forecast': {
                'median': [round(x, 2) for x in q[median_idx, :].tolist()],
                'confidence_80': {
                    'lower': [round(x, 2) for x in q[lower_idx, :].tolist()],
                    'upper': [round(x, 2) for x in q[upper_idx, :].tolist()]
                }
            },
            'prediction': {
                'change': round(float(q[median_idx, -1]) - current_price, 2),
                'change_pct': round((float(q[median_idx, -1]) - current_price) / current_price * 100, 2)
            }
        }
    except Exception as e:
        raise HTTPError(500, f'Forecast failed: {str(e)}')

@get('/api/info')
def info():
    return {
        'model': 'chronos-2',
        'device': device,
        'cuda': torch.cuda.is_available(),
        'endpoints': {
            '/api/stock-forecast': 'POST - Stock forecast (params: prices, horizon)',
            '/api/info': 'GET - API info'
        }
    }

if __name__ == '__main__':
    run(host='0.0.0.0', port=5003, debug=True)
Overview
HTTP API that runs Amazon’s Chronos-2 transformer for stock price forecasting. POST price array, get probabilistic predictions with confidence intervals.
Single endpoint: /api/stock-forecast
- Input:
{"prices": [100, 102, ...], "horizon": 10} - Output: median forecast + 80% confidence intervals + price change
Uses pipeline.predict() with limit_prediction_length=False for auto-regressive unrolling - enables long-horizon forecasts beyond the model’s native prediction window. Runs on GPU with bfloat16 for memory efficiency.
72 lines. Could easily be 300+ with typical issues: duplicate forecasting logic across endpoints, unnecessary helper abstractions, generic + specific endpoints doing the same thing, excessive comments explaining obvious code, bloated info endpoints with static metadata. This avoids all that.